Run fully asynchronous verl examples#
2026-09-24
1 min read time
This guide shows how to run fully asynchronous verl examples on AMD GPUs with ROCm. It covers preparing data and models, launching fully asynchronous GRPO training on a vision-language model with Megatron, and running fully asynchronous DAPO math reasoning training with FSDP2.
Megatron example#
The geo3k_qwen25vl_7b_megatron_4_4.sh example launches fully asynchronous GRPO training for Qwen2.5-VL-7B-Instruct on the Geometry3k vision-math dataset using verl’s fully asynchronous policy with the Megatron trainer configuration.
Download and prepare the data models:
export HF_TOKEN=your_token
# or: hf auth login
cd /workspace/verl
bash verl/experimental/fully_async_policy/shell/data_model_preparation/prepare_geo3k_qwen25vl_7b_megatron_4_4.sh
Run the example:
export HF_MODEL_PATH=${HOME}/models/Qwen2.5-VL-7B-Instruct
export WANDB_MODE=offline
unset NVTE_FLASH_ATTN NVTE_FUSED_ATTN NVTE_UNFUSED_ATTN
export TE_HIPBLASLT_ALGO_SELECTION=1   # if fails, try 2, 3, ...
unset TE_HIPBLASLT_TUNING_RUN_COUNT TE_HIPBLASLT_ALGO_SAVE
cd /workspace/verl
bash verl/experimental/fully_async_policy/shell/geo3k_qwen25vl_7b_megatron_4_4.sh
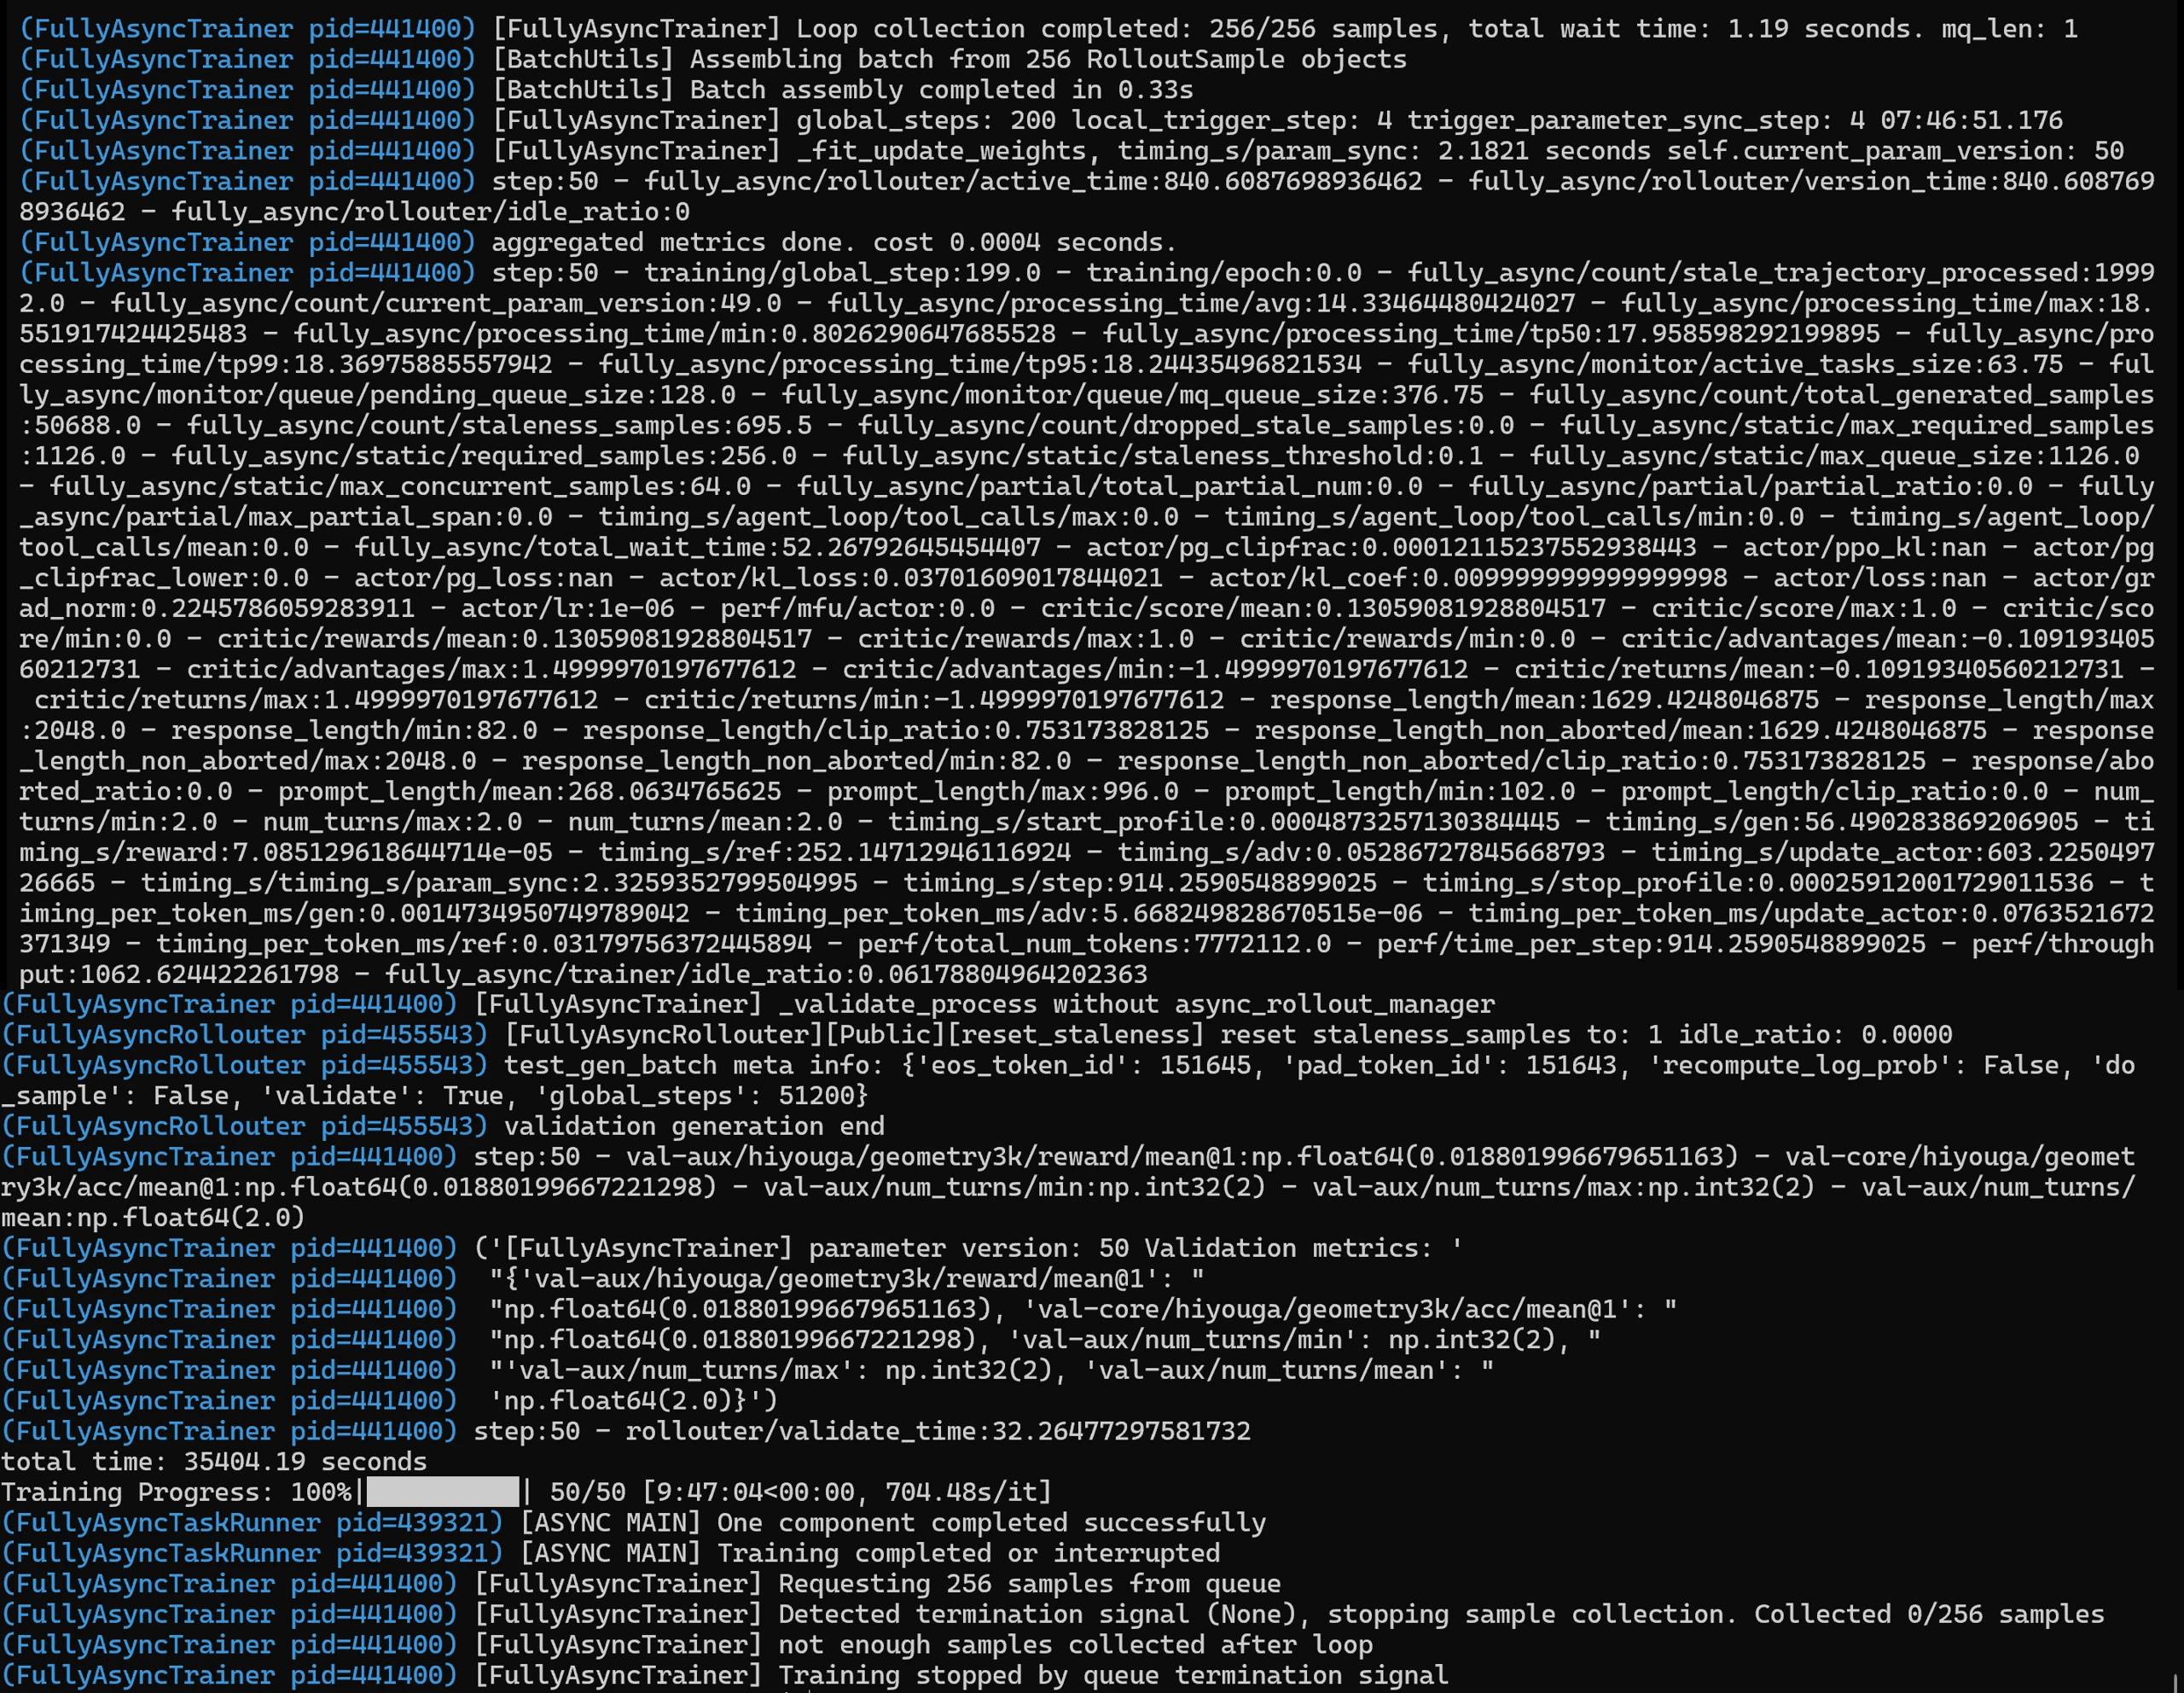
This example will take several hours to run. Once the example completes, the output should resemble the following:
DAPO example#
The dapo_7b_math_fsdp2_4_4.sh
example launches fully asynchronous DAPO reinforcement learning training using Qwen2.5-Math-7B on math reasoning tasks.
Download and prepare the data models:
export HF_TOKEN=your_token
# or: hf auth login
cd /workspace/verl
bash verl/experimental/fully_async_policy/shell/data_model_preparation/prepare_dapo_7b_math_fsdp2_4_4.sh
Update dependencies:
pip install --upgrade 'accelerate>=1.14.0'
Run the example:
cd /workspace/verl
bash verl/experimental/fully_async_policy/shell/dapo_7b_math_fsdp2_4_4.sh
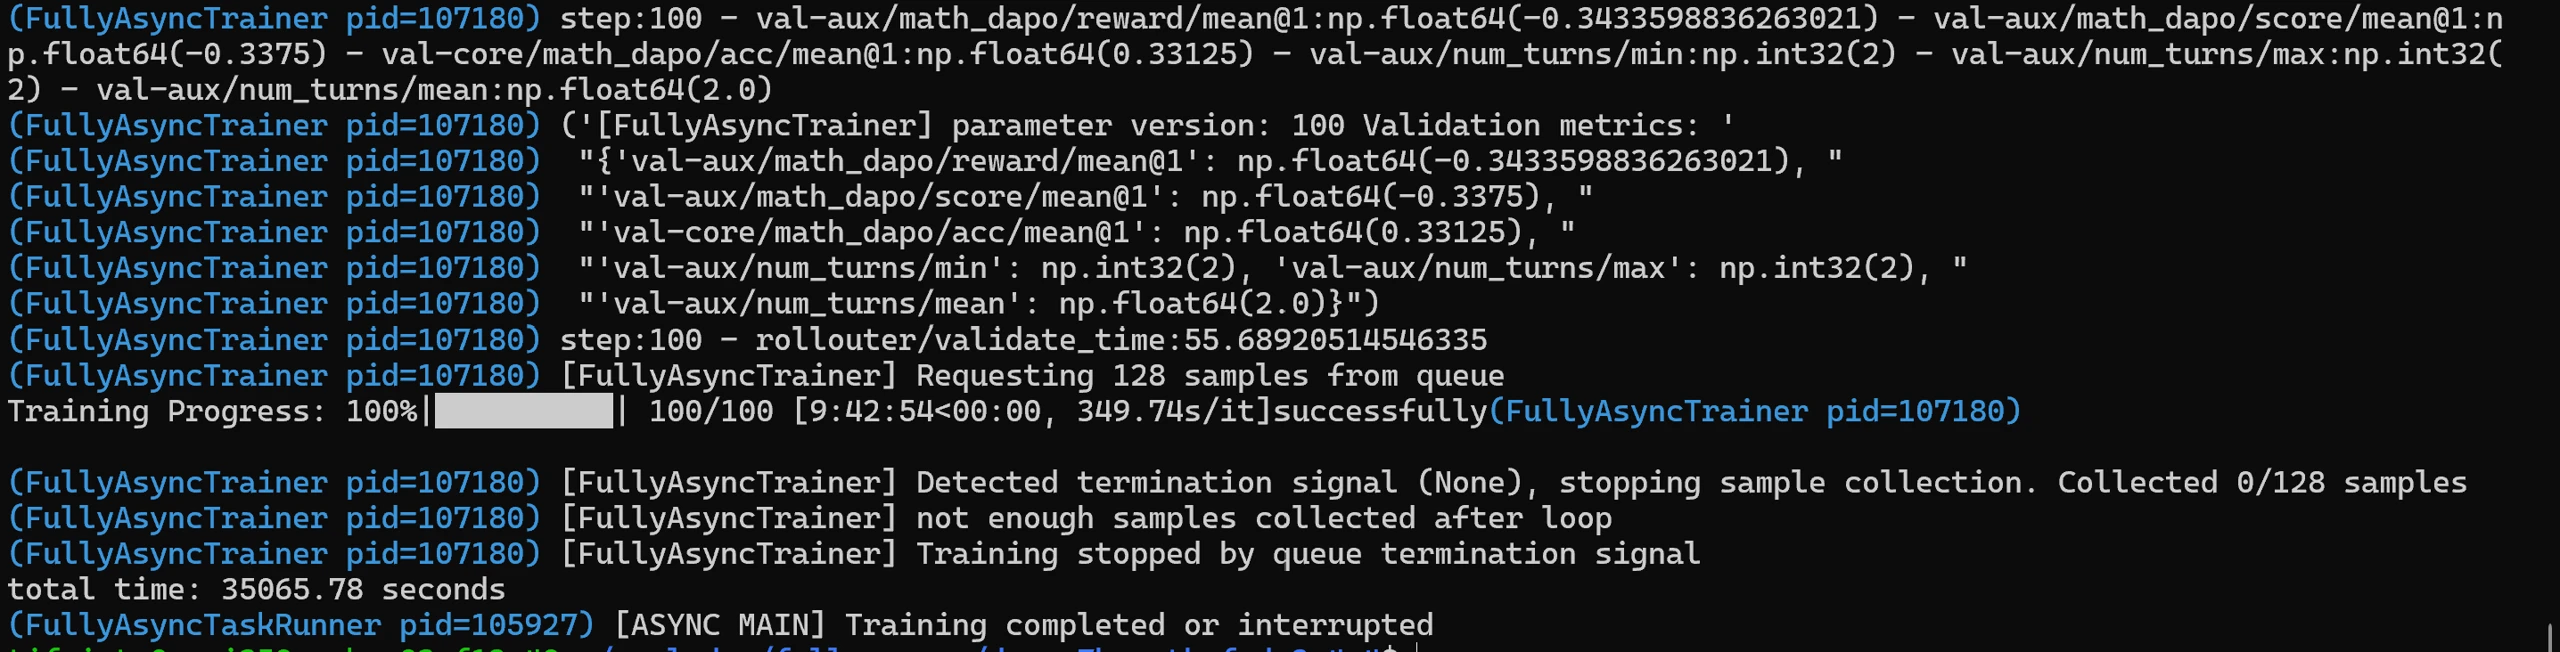
This example will take several hours to run. Once the example completes, the output should resemble the following: